AI & Business Growth, AI developement, Artificial intelligence (AI)
RAG vs Fine-Tuning Explained: Cost, Accuracy, and Best Use Cases
By Manahil Umer · · Updated
Artificial intelligence can now power customer support, internal search, workflow automation, and decision-making tools. However, once businesses decide to build an AI-driven product, they quickly face a critical architecture question:
Should you use Retrieval-Augmented Generation (RAG) or Fine-Tuning?
Choosing the wrong approach can lead to rising costs, outdated responses, and ongoing maintenance headaches.
In this guide, we’ll break down both approaches in plain language, explore their real business impact, compare costs and accuracy, and help you decide which method fits your product best.
If you’re planning an AI chatbot, enterprise assistant, or automation tool, this article will give you the clarity you need.
Why does the choice between RAG and fine-tuning matter?
Many teams assume choosing between RAG and fine-tuning is just a technical choice. In reality, it affects:
- Development cost
- Time to launch
- Accuracy of responses
- Scalability of your system
- Long-term maintenance effort
For example, an AI trained incorrectly may require full rebuilding within months. Meanwhile, a well-designed architecture can support growth for years.
That’s why modern AI implementation starts with choosing the right customization strategy.
| Feature | RAG | Fine-Tuning |
|---|---|---|
| Knowledge updates | Instant via database | Requires retraining |
| Initial cost | Lower | Higher |
| Accuracy type | Fact-based accuracy | Behavioral consistency |
| Scalability | Easy with new documents | Harder across domains |
| Maintenance | Update data only | Retrain periodically |
| Best for | Knowledge assistants, search, support | Classification, structured tasks |
What Is Retrieval-Augmented Generation (RAG)?
Retrieval-Augmented Generation, or RAG, enhances an AI model by connecting it to external knowledge sources.
Instead of storing information inside the model, RAG retrieves relevant data in real time and uses that context to generate answers.
Think of it like this:
Fine-tuning teaches the AI what to know. RAG teaches the AI where to look.
How does RAG work?
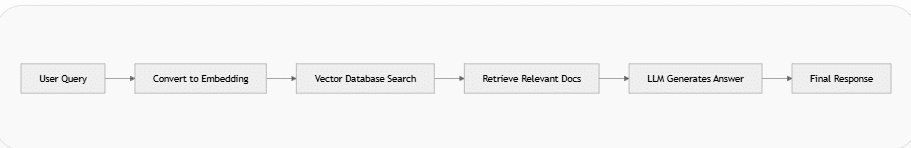
RAG System Workflow Diagram
Here’s the typical RAG workflow:
- A user asks a question.
- The system converts the query into embeddings.
- Next, a vector database searches for the most relevant documents.
- Then, the relevant content is retrieved.
- Finally, the AI generates a response using that context.
This happens in seconds.
For instance:
If an employee asks, “What’s our refund policy for enterprise clients?”
A RAG system searches internal policy documents and answers using the latest version.
No retraining required.
Why do businesses usually start with RAG?
1. Faster Deployment With Lower Initial Cost
Unlike fine-tuning, RAG doesn’t require training the model itself.
You build:
- A document pipeline
- Embeddings generation
- A vector database
- Retrieval logic
Because you skip the expensive training phase, your AI system can launch much faster.
For startups or companies testing AI for the first time, this reduces financial risk.
2. Real-Time Knowledge Updates
Real-time knowledge updates are where RAG is strongest.
If your company updates:
- Product pricing
- Policies
- Technical documentation
- Compliance rules
You don’t need to retrain the model. Instead, you simply update the database.
As a result, your AI immediately uses the latest information.
No retraining cycle. No downtime. No version conflicts.
This makes RAG perfect for:
- SaaS platforms
- eCommerce systems
- HR knowledge assistants
- Customer support automation
3. Handles Massive Knowledge Bases Smoothly
For example, large organizations often have…
- Thousands of PDFs
- Product manuals
- Internal SOPs
- Support tickets
- Compliance documents
RAG uses semantic search and vector indexing to find relevant information quickly, even inside huge datasets.
Consequently, instead of guessing, the AI answers using actual source material.
As a result, this improves both relevance and reliability.
4. Transparent and Verifiable Answers
One major concern with AI is hallucination.
Because responses are grounded in retrieved documents, RAG significantly reduces this risk.
Many systems can even:
- Display source links
- Log references used
- Provide audit trails
This transparency builds trust and supports regulatory requirements.
For industries like fintech, healthcare, and enterprise SaaS, this is essential.
Example: How RAG Uses Retrieved Context
Limitations of RAG
RAG has trade-offs.
- Requires a good search system
- Needs document formatting and indexing
- Responses depend on retrieval quality
- May increase latency slightly
Nevertheless, for most business use cases, these trade-offs are worth it.
What Is Fine-Tuning?
Fine-tuning takes a different approach from RAG.
Instead of retrieving external data, you train the AI model itself using your domain-specific dataset.
As a result, the model learns…
- Your terminology
- Your workflow logic
- Your tone of communication
- Your response patterns
After fine-tuning, the AI internally “knows” how to respond in your domain.
How does fine-tuning work?
Sample Fine-Tuning Training Record
A simplified workflow:
- Collect domain-specific data.
- Next, format it into training pairs.
- Then, train the model.
- Afterward, validate its performance.
- Finally, deploy the customized model.
For example:
A logistics company may fine-tune a model on thousands of historical support chats.
The AI then learns:
- How to respond professionally
- How to categorize issues
- How to escalate complex cases
This improves behavioral consistency.
Where Fine-Tuning Excels
1. Highly Consistent Output Format
Fine-tuning works well when responses must follow strict patterns.
Examples include:
- Ticket classification
- Structured summaries
- Formatted reports
- Decision workflows
Because the model learns these patterns during training, outputs remain consistent.
2. Strong Domain Language Understanding
Some industries use specialized terminology.
Fine-tuning helps AI understand:
- Medical phrasing
- Legal terminology
- Financial reporting language
- Technical engineering jargon
This reduces misunderstandings and improves precision.
3. Faster Response Time at Scale
Since the knowledge lives inside the model, there’s no retrieval step.
This can reduce latency in high-volume systems.
For applications handling thousands of requests per minute, that performance gain matters.
Cost Comparison: RAG vs Fine-Tuning
The choice between RAG and fine-tuning directly affects your budget.
| Cost Factor | RAG | Fine-Tuning |
|---|---|---|
| Setup time | Short | Longer |
| Compute cost | Low | High during training |
| Update cost | Minimal | Requires retraining |
| Scaling cost | Database growth | Model management |
Initial Development Cost
RAG is usually cheaper upfront.
Why?
Because you avoid:
- Training compute costs
- Dataset preparation complexity
- Multiple experiment cycles
Instead, you focus on building a retrieval system.
Fine-tuning, on the other hand, requires:
- Data cleaning
- Annotation
- Training infrastructure
- Testing iterations
This makes initial investment higher.
Long-Term Operational Cost
Here’s the interesting part.
RAG ongoing costs include:
- Vector database hosting
- Storage scaling
- Slightly higher token usage
- Retrieval compute
Fine-tuning ongoing costs include:
- Model hosting
- Periodic retraining
- Dataset updates
- Performance monitoring
If your knowledge changes frequently, RAG remains cheaper long-term.
If tasks are stable and repeated millions of times, fine-tuning can eventually become more cost-efficient.
Which is more accurate, RAG or fine-tuning?
The real answer is: It depends on what “accuracy” means for your use case.
RAG Accuracy Strength
RAG delivers stronger accuracy when:
- Answers must reflect the latest information
- Knowledge changes frequently
- Source verification matters
Because it pulls from updated documents, it reduces outdated responses. If accuracy means factual correctness from current data, RAG often wins.
Fine-Tuning Accuracy Strength
Fine-tuning excels when accuracy means:
- Consistent decision logic
- Reliable classification
- Branded tone of voice
- Structured output
For example:
A fine-tuned AI can reliably decide:
- Whether to approve a request
- How to categorize a ticket
- Which workflow to trigger
This behavioral reliability is harder to achieve with RAG alone.
Maintainability: The Hidden Cost Most Teams Miss
Launch is exciting. Maintenance is reality.
Let’s compare both approaches over time.
Maintaining a RAG System
RAG maintenance usually involves:
- Adding new documents
- Updating old ones
- Re-indexing the database
- Improving retrieval filters
No retraining required.
This makes it easier for:
- Growing startups
- Content-heavy organizations
- Rapidly evolving industries
Maintaining a Fine-Tuned Model
Fine-tuned systems require more lifecycle management.
You must:
- Monitor output drift
- Update datasets
- Retrain periodically
- Re-test accuracy
This requires machine learning expertise and ongoing budget.
For stable workflows, this is manageable. For fast-changing businesses, it becomes expensive.
The Hybrid Approach: What Modern AI Systems Use
Most enterprise AI platforms now combine RAG and fine-tuning.
A hybrid system might:
- Use fine-tuning for tone, structure, and logic
- Use RAG for real-time knowledge retrieval
Example:
A customer support AI could:
- Be fine-tuned on brand communication style
- Retrieve product info using RAG
This delivers:
- Fresh knowledge
- Consistent behavior
- High reliability
Hybrid architecture often provides the best long-term flexibility.
How to Choose the Right Approach for Your Business
Ask yourself these questions.
Choose RAG If:
- Your data updates frequently
- You manage large document libraries
- You need traceable answers
- You want a faster launch time
- You want a lower upfront cost
Choose Fine-Tuning If:
- Tasks are repetitive and stable
- Output format must be strict
- Tone consistency is critical
- You have curated training data
- Latency must be minimal
Choose Hybrid If:
- You need both fresh knowledge and behavioral control
- Your AI will serve multiple departments
- You plan long-term scaling
Real Business Impact of Choosing Correctly
The right AI architecture improves:
- Customer response accuracy
- Employee productivity
- Automation reliability
- Operational cost efficiency
- User trust in AI systems
The wrong architecture often leads to:
- Frequent rebuilds
- Rising infrastructure costs
- Outdated AI responses
- Poor user adoption
This is why companies increasingly rely on experienced AI implementation partners like The Right Software to design scalable solutions from the start.
Final Thoughts
RAG and fine-tuning aren’t competitors. They’re tools for different challenges.
- RAG excels in dynamic knowledge environments and rapid deployment.
- Fine-tuning shines in stable workflows and consistent behavioral outputs.
- Hybrid systems combine both for enterprise-grade AI performance.
Choosing the right approach early saves cost, reduces risk, and ensures your AI product scales smoothly.
Choosing the Right Approach
Planning an AI chatbot, automation platform, or intelligent assistant?
Book a free consultation with The Right Software today and let our experts help you choose the most cost-effective, scalable AI architecture for your business.
Frequently asked questions
What is the difference between RAG and fine-tuning?
RAG leaves the model unchanged and retrieves relevant data from external sources at question time. Fine-tuning trains the model on your domain-specific examples so the behaviour is built into the model.
Is RAG cheaper than fine-tuning?
Usually, at the start. RAG avoids training compute, dataset annotation and repeated experiments. Its ongoing costs are vector database hosting, storage and retrieval. Fine-tuning has higher setup costs plus periodic retraining, but can be cheaper for very high-volume, stable tasks.
Which is more accurate, RAG or fine-tuning?
It depends on the kind of accuracy. RAG is more accurate for current facts and verifiable answers. Fine-tuning is more accurate for consistent classification, decision logic, tone and output structure.
When should I combine RAG and fine-tuning?
When you need both fresh knowledge and controlled behaviour, for example a support assistant fine-tuned on your brand's communication style that retrieves product information with RAG.
How does a RAG system answer a question?
It converts the question into embeddings, searches a vector database for the most relevant documents, retrieves that content and gives it to the model as context for the answer, typically within seconds.